
Every few months, local AI hardware settles into a comfortable cliché—and then a new silicon bus breaks it. In late 2026, the three-way fight for desk-side 128 GB+ unified memory comes down to AMD Strix Halo (Ryzen AI Max+ 395), NVIDIA DGX Spark (GB10), and Apple’s August 2026 Mac Studio (M5 Max / M5 Ultra).
Most comparisons online still quote outdated M4 Max / M3 Ultra tables or stop at spec-sheet slogans (“Apple has bandwidth, NVIDIA has CUDA, AMD is cheaper”). That misses the actual engineering trade-offs: how MoE vs. dense models behave on a 256-bit bus, why Strix Halo hits a 64k–128k context cliff under ROCm, and what 24/7 European electricity does to the real three-year bill.
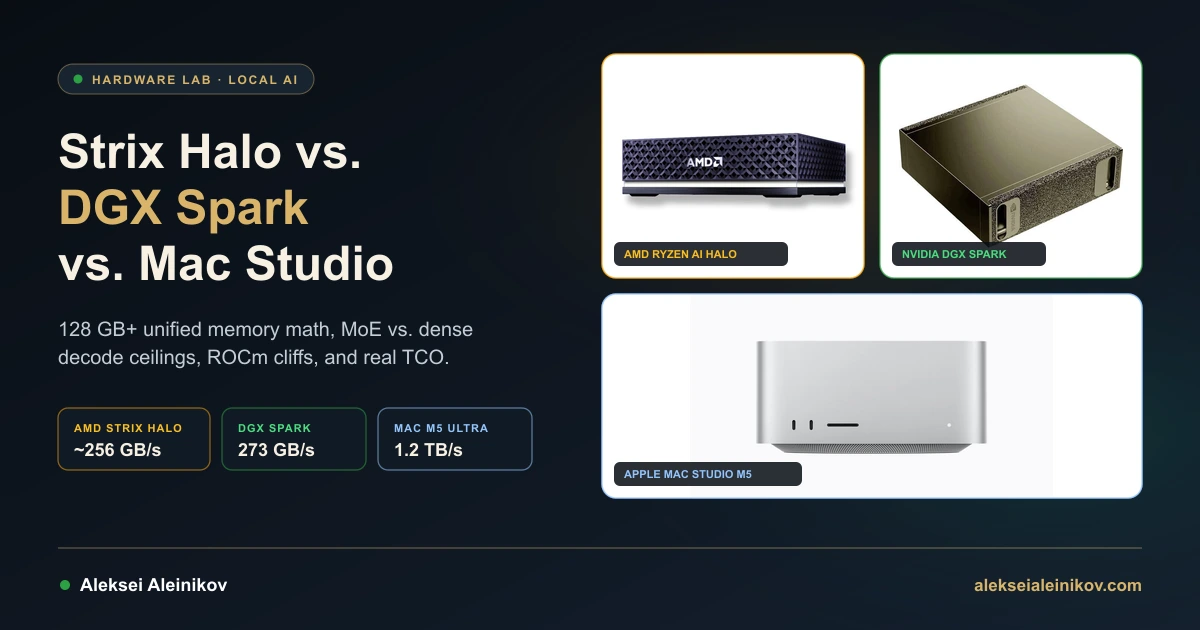
The three contenders in November 2026
Unlike discrete GPUs—where an RTX 5090 screams at ~1,792 GB/s until it slams into a 32 GB VRAM wall—all three desktop contenders share one large memory pool between CPU and GPU. That single decision changes what fits on your desk, how fast it thinks, and what software breaks.
| Specification | AMD Strix Halo (Ryzen AI Max+ 395) |
NVIDIA DGX Spark (GB10) |
Apple Mac Studio (M5 Max / M5 Ultra) |
|---|---|---|---|
| CPU + GPU | 16-core Zen 5 + Radeon 8060S (40 CUs, RDNA 3.5) | 20-core Armv9 + Blackwell GPU (1,000 TOPS FP4) | 18-core + 32/40-core GPU (Max) · 30–36-core + 64/80-core GPU (Ultra) |
| Unified Memory | 128 GB LPDDR5x-8000 (up to 96 GB BIOS VGM) | 128 GB coherent LPDDR5x | 36–128 GB (Max) · 96–512 GB (Ultra) |
| Memory Bandwidth | ~215–256 GB/s (256-bit bus) | 273 GB/s (256-bit bus) | 460 / 614 GB/s (Max) · 1.2 TB/s (Ultra) |
| Networking / I/O | 2.5GbE (Framework/EVO-X2) or Dual 10GbE + PCIe x16 (MS-S1 Max) | 200 Gb/s ConnectX-7 RDMA (dual-node clustering) | Thunderbolt 5, 10GbE, Wi-Fi 7 |
| Software Stack | x86_64 Linux / Windows · ROCm, Vulkan, llama.cpp |
DGX OS (Arm Linux) · native CUDA, vLLM, TensorRT-LLM | macOS · MLX, Metal, llama.cpp |
| Idle Power | ~30 W | ~45 W | ~9 W |
| 2026 Entry Price (128 GB) | ~$1,999–$2,499 (Framework / MS-S1 Max) |
$4,699 MSRP (retail up to $6,950) | ~$3,899–$4,099 (M5 Max) · $5,499+ (M5 Ultra 96 GB+) |
Meet the actual boxes
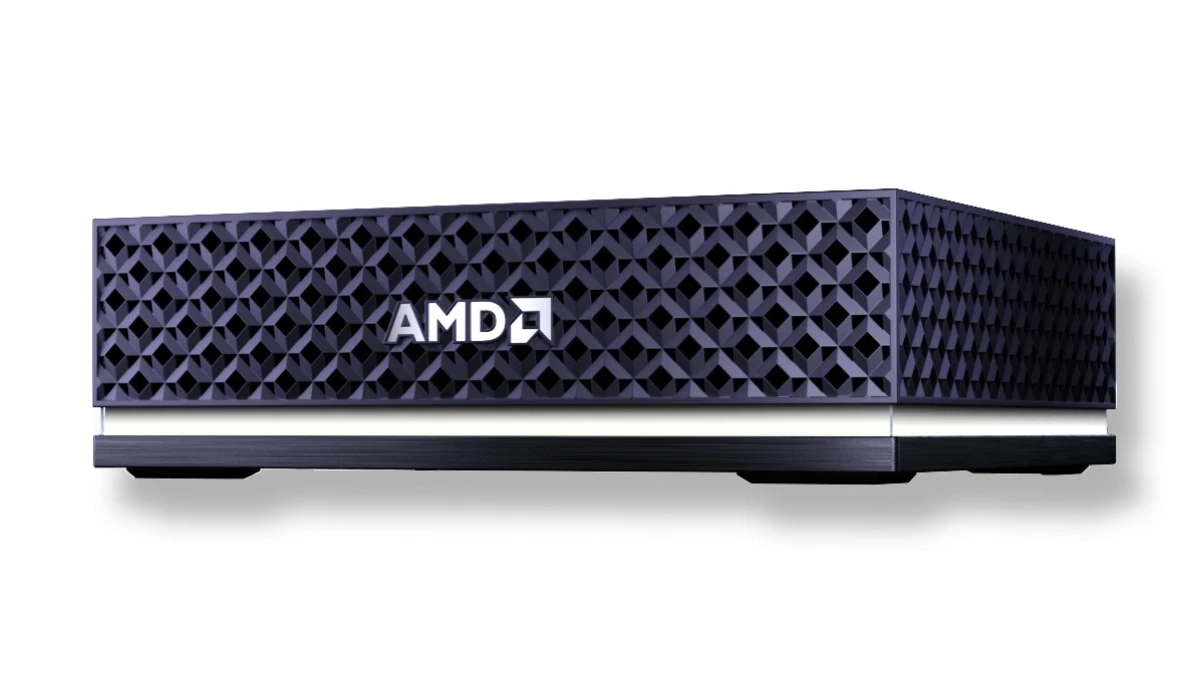
A common mistake in Strix Halo coverage is treating it as one generic mini-PC. In practice, buyers choose among three distinct chassis:
- Framework Desktop (~$1,999 base for 128 GB): A 4.5-liter modular Mini-ITX workstation with swappable front tiles, dual M.2 NVMe slots, and clean Linux support.
- GMKtec EVO-X2 (~$2,199–$3,499): A compact Windows 11 Pro mini-PC aimed at turnkey desktop use.
- Minisforum MS-S1 Max (~$2,499): A slightly larger mini-workstation that adds dual 10GbE ports and a physical PCIe x16 slot—making it the standout Strix Halo option for homelab clustering and NAS integration.
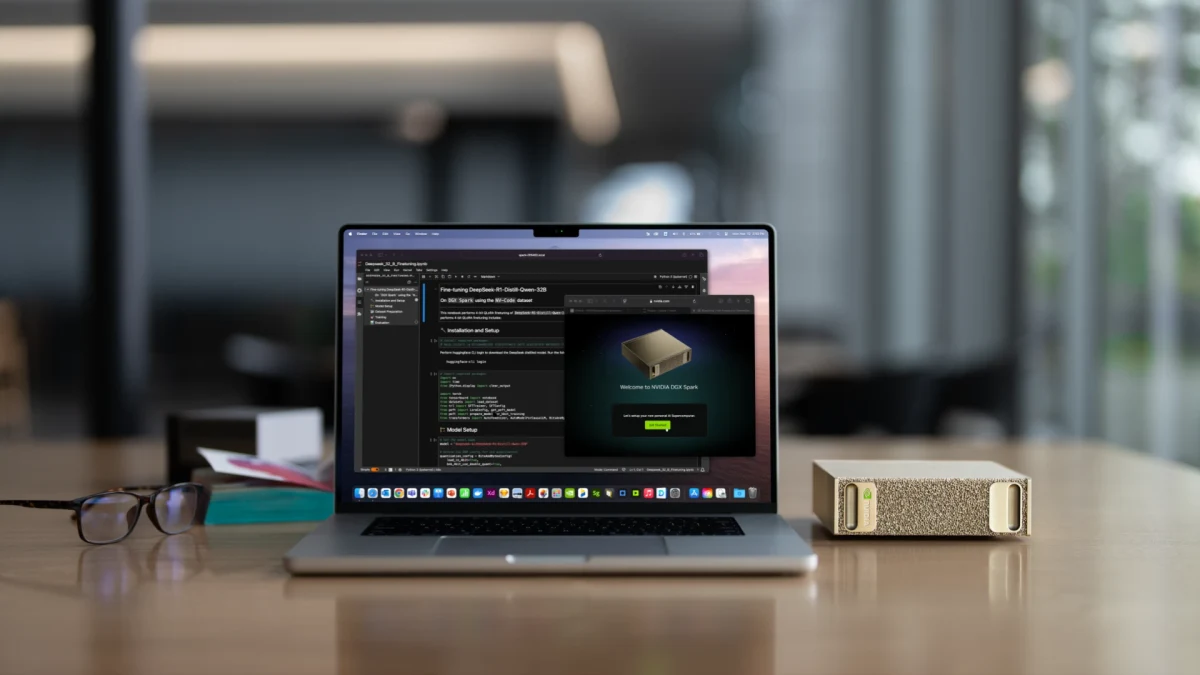
On the NVIDIA side, DGX Spark remains the smallest turnkey native CUDA box with 128 GB of memory. As we broke down in our dedicated DGX Spark architecture analysis, its 273 GB/s bus is intentionally modest so NVIDIA can keep the chassis at 150 × 150 mm (~140 W SoC TDP) while packing 1 PFLOP of sparse FP4 compute and 200 Gb/s ConnectX-7 RDMA.
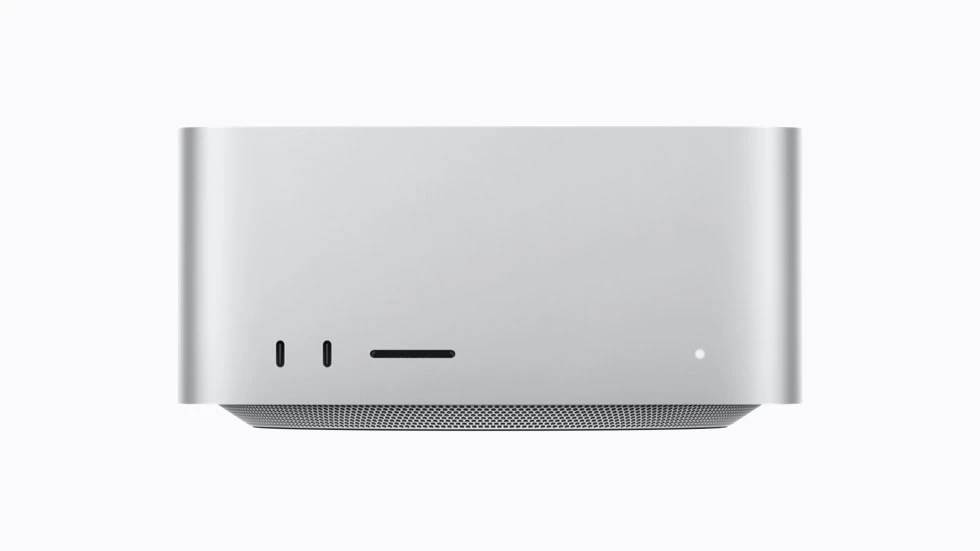
Apple’s August 2026 Mac Studio refresh skipped an M4 Ultra entirely and moved straight to M5 Max (with 460 GB/s on the 32-core GPU tier and 614 GB/s on the 40-core GPU tier) and M5 Ultra (1.2 TB/s and up to 512 GB unified memory), embedding Neural Accelerators directly inside each GPU core to cut prompt-prefill lag that used to handicap older Apple Silicon generations.
Decode speed: why Dense 70B stalls and MoE flies
Single-user LLM token generation (decode) is memory-bandwidth bound: to emit one token, the GPU must stream every active weight from RAM. If you want a refresher on how quantization shrinks weight footprints before hitting that bus, see our quantization guide for consumer hardware.
Roofline decode ceiling ≈ Memory_Bandwidth (GB/s) ÷ Active_Model_Size (GB)Plug a classic 70B dense Q4_K_M model (~40.5 GB active per token) into that equation:
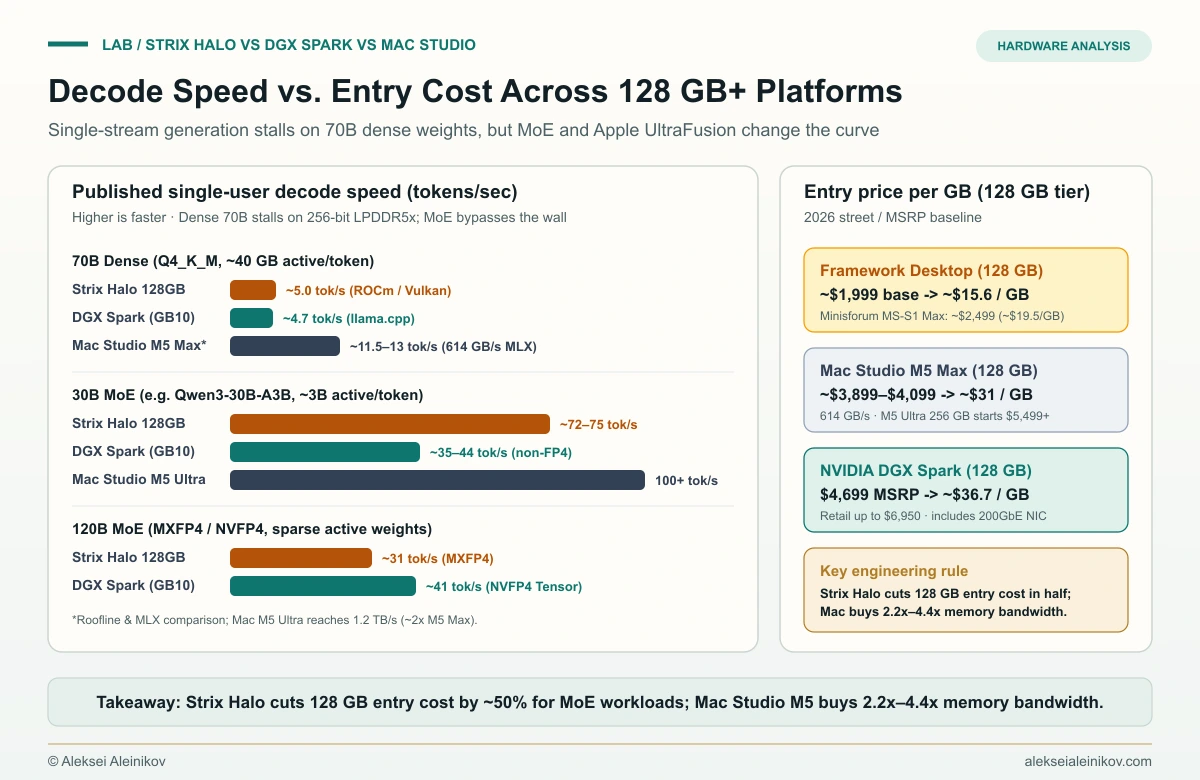
- Strix Halo (~256 GB/s): theoretical ceiling ~6.3 tok/s → ~5.0 tok/s in published
llama.cppruns. - DGX Spark (273 GB/s): theoretical ceiling ~6.8 tok/s → ~4.7 tok/s in
llama.cpp(~2.7–3.0 tok/s in FP8 vLLM). - Mac Studio M5 Max (614 GB/s) / M5 Ultra (1.2 TB/s): 2.2× to 4.4× wider bus → ~11.5–13+ tok/s on M5 Max and 20+ tok/s on M5 Ultra.
Now switch from a dense 70B model to Mixture-of-Experts (MoE) architectures—such as Qwen3-30B-A3B (~3B active parameters per token) or 120B MXFP4/NVFP4 MoE—where 128 GB holds the full expert pool in RAM while only a fraction streams per token:
- 30B MoE: Strix Halo reaches ~72–75 tok/s; DGX Spark hits ~35–44 tok/s (when not using FP4 Tensor paths); Mac Studio M5 Ultra pushes past 100+ tok/s.
- 120B MoE (MXFP4 / NVFP4): Strix Halo sustains ~31 tok/s; DGX Spark pulls ahead at ~41 tok/s thanks to native Blackwell NVFP4 Tensor Cores.
Architecture traps: BIOS VGM, the ROCm context cliff, and CUDA parity
Hardware specs only tell half the story. Once you load a 70B–120B model with a real coding-agent context window (32k to 128k tokens), the driver stack decides whether your box stays fast or collapses.
1. Strix Halo’s 64k–128k ROCm context cliff
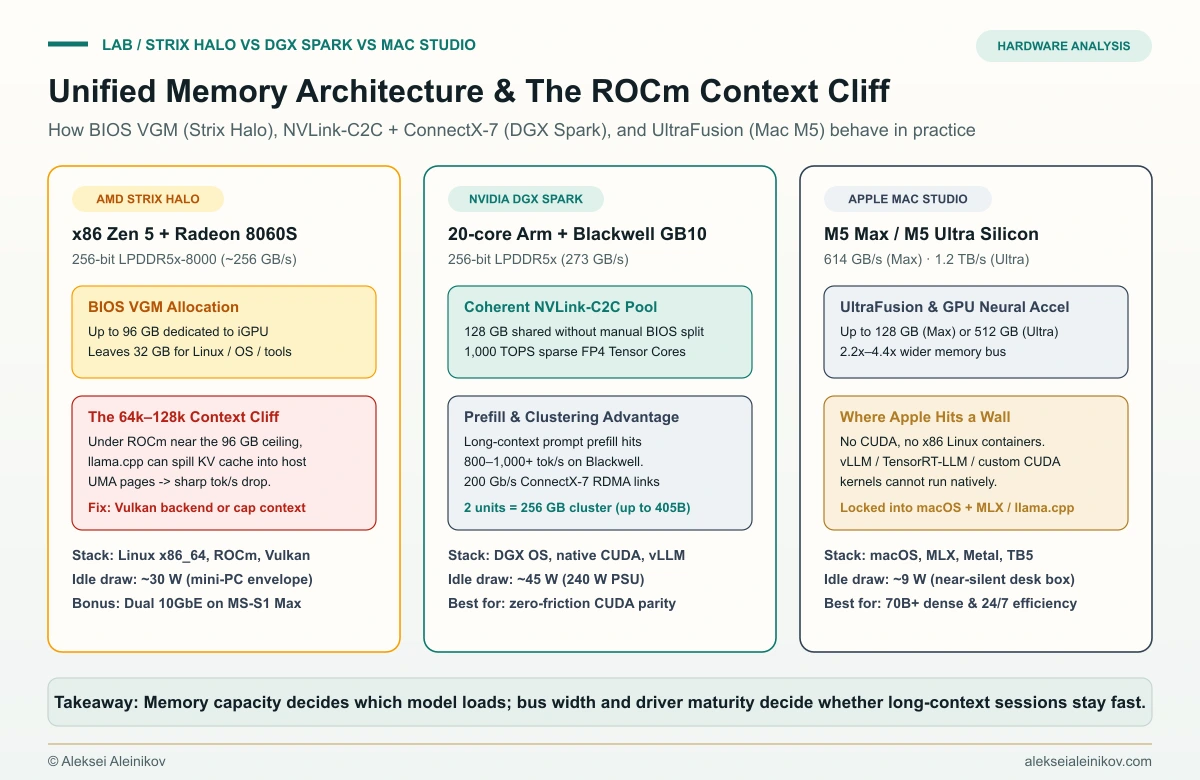
On Windows and Linux, Strix Halo exposes its 128 GB pool via Variable Graphics Memory (VGM) in BIOS—allowing up to 96 GB to be dedicated to the Radeon 8060S iGPU while leaving 32 GB for the OS.
In practice, r/LocalLLaMA builders uncovered a nasty edge case: when you push VGM near 96 GB and run 64k–128k context under ROCm in llama.cpp, KV-cache allocations can spill back into host UMA pages, causing token generation speed to fall off a cliff. Community llama.cpp benchmarks on Strix Halo (gfx1151) also show a clear split between Vulkan (RADV) and tuned ROCm:
llama.cpp Backend (Strix Halo gfx1151) |
Prompt Prefill (TTFT) | Token Decode (tg/s) |
Stability & Setup |
|---|---|---|---|
ROCm / HIP (ROCBLAS_USE_HIPBLASLT=1 + rocWMMA) |
+28% to +42%+ faster | Competitive | Sensitive to ROCm/LLD versions & 96 GB UMA spill |
Vulkan (RADV) |
Solid baseline | +10% to +19% faster | Plug-and-play across Mesa updates; avoids ROCm UMA cliff |
Two practical rules follow from that split:
- Use Vulkan (
RADV) for interactive chat, coding bursts, and long-context stability without fighting ROCm flags; - Use tuned ROCm when batch prompt ingestion (large RAG chunks or whole-repo prefill) dominates your latency.
2. Why DGX Spark costs twice as much—and when it is worth it
At $4,699 MSRP (~$36.7/GB, vs. ~$15.6/GB on a base 128 GB Framework Desktop), DGX Spark is hard to justify for casual local chat. Where it earns its markup is engineering frictionlessness:
- Native CUDA + vLLM + TensorRT-LLM: No ROCm container debugging, no macOS Metal workarounds—the exact inference stack you deploy on cloud L4/H100/B200 GPUs runs locally.
- Compute-bound prefill: Reading a 64k-token repository into context is compute-bound, not bandwidth-bound. Blackwell’s 1 PFLOP FP4 Tensor Cores push prefill to 800–1,000+ tok/s.
- 200 Gb/s ConnectX-7 RDMA: Plug two DGX Spark boxes directly together with a QSFP cable and you get a 256 GB cluster capable of loading quantized 405B-class models—something neither a single Mac Studio M5 Max nor a consumer mini-PC can match without high-latency Thunderbolt/Ethernet bottlenecks.
3. Apple Mac Studio M5: silent brute-force bandwidth, zero CUDA
If your workflow lives in MLX, llama.cpp, or LM Studio, the M5 Max (614 GB/s) and M5 Ultra (1.2 TB/s, up to 512 GB) remain unbeatable for dense 70B+ models and multi-hundred-billion-parameter local weights. The catch is structural: no CUDA, no native x86 Linux containers, and steep BTO pricing once you step into 256 GB or 512 GB tiers.
European TCO: idle watts matter when electricity is EUR 0.32/kWh
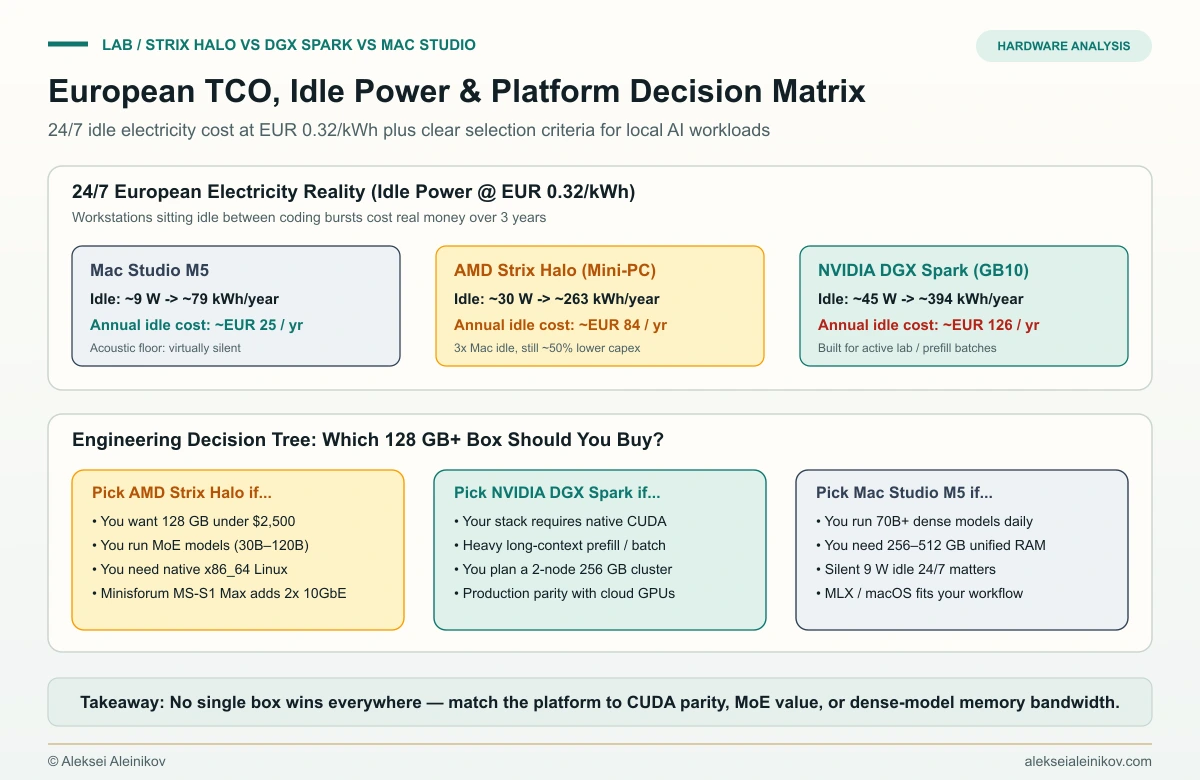
Benchmarks usually measure peak watts under load, even though a developer workstation spends 80–90% of a 24/7 week sitting idle between prompts, builds, and overnight agent runs. At a typical European electricity tariff of EUR 0.32/kWh, idle draw compounds quietly:
- Mac Studio M5 (~9 W idle): ~79 kWh/year → ~EUR 25/year (and virtually inaudible).
- AMD Strix Halo Mini-PC (~30 W idle): ~263 kWh/year → ~EUR 84/year (~3.3× Mac idle, still ~50% lower hardware capex than DGX Spark).
- NVIDIA DGX Spark (~45 W idle): ~394 kWh/year → ~EUR 126/year.
Decision matrix: which 128 GB+ workstation should you buy?
- Choose AMD Strix Halo (
Framework DesktoporMinisforum MS-S1 Max) if you want 128 GB under $2,500, run MoE models (30B–120B), and need standard x86_64 Linux (plus dual 10GbE and a PCIe slot on the MS-S1 Max for homelab/NAS pipelines)—and you are comfortable tuning Vulkan vs. ROCm for 64k+ contexts. - Choose NVIDIA DGX Spark if your team requires zero-friction CUDA / vLLM / TensorRT-LLM parity, heavy long-context prefill for coding agents, or a 256 GB dual-node RDMA cluster over ConnectX-7—and the $4,699+ price is an R&D budget item rather than a personal expense.
- Choose Apple Mac Studio (
M5 Max/M5 Ultra) if you run 70B+ dense models every day, need 256–512 GB of unified RAM in a single silent box, care about ~9 W idle power, and are happy living inside macOS + MLX.
Author’s pick: why I would test AMD Strix Halo first
If I were buying one 128 GB desk-side box with my own money to put through its paces in a homelab, I would try AMD Strix Halo first—specifically a Framework Desktop or Minisforum MS-S1 Max. At ~$1,999–$2,499, you get 128 GB of unified memory in a standard x86_64 Linux environment for roughly half the price of a DGX Spark ($4,699), without locking your containers and tooling into macOS. Yes, 70B dense weights crawl at ~5 tok/s, and you have to watch the ROCm vs. Vulkan trade-off on long contexts—but for running 30B–120B MoE coding models, local agent loops, and Dockerized homelab services side by side, Strix Halo gives you the highest engineering freedom per euro spent.
Key takeaways
- Memory capacity decides what loads; memory bandwidth decides how fast dense models read; MoE architecture lets 256–273 GB/s buses punch above their weight.
- Strix Halo is the clear value disruptor of late 2026 (~$15.6–$19.5/GB), cutting the entry price of 128 GB local AI roughly in half compared to DGX Spark.
- DGX Spark wins on CUDA parity, FP4 prefill, and ConnectX-7 clustering—not raw single-stream decode speed.
- Mac Studio M5 wins on raw bandwidth (614 GB/s–1.2 TB/s), 512 GB ceiling, and 9 W idle efficiency, at the cost of macOS lock-in.
From the community
Discussion on Mastodon & Bluesky
Replies to this article from the open web, pulled in live. No ads, no tracking scripts.
Reply there — it shows up here automatically.